Analysing website access logs with grep, awk and a free ASN database
What started it all
For a few weeks, the dashboard for one of our hosting servers showed a pattern I didn’t like: CPU and bandwidth rising and falling together, in surges.
Bandwidth on its own is usually boring. Somebody downloading a big PDF, a product image going viral. CPU moving in step with it means PHP: lots of full, uncached WordPress page renders, all at once. And this is a capable server. It takes a lot of uncached page loads to make it look busy.
So who was asking for all those pages? The server keeps the answer in plain text, in every site’s access.log. This walk-through shows how I counted it on three WooCommerce shops using nothing more exotic than grep, awk, sort | uniq -c and a free IP-to-network database, and what the numbers turned out to be.
Always start with eyeballing the logs
Open a WooCommerce site’s access.log and a real visitor looks like this. One page request, then within a second or two the fonts, stylesheets and the AJAX calls WooCommerce fires on every page (wc-ajax=get_refreshed_fragments refreshes the mini-basket):
203.0.113.45 - - [10/Sep/2026:12:12:04 +0100] "GET /product/example-paper-a/ HTTP/2.0" 200 83649 "https://www.google.com/" "Mozilla/5.0 (iPhone; CPU iPhone OS 18_7 like Mac O…"
203.0.113.45 - - [10/Sep/2026:12:12:06 +0100] "GET /wp-content/themes/astra/assets/fonts/astra.woff HTTP/2.0" 200 3381 "https://www.example.com/product/example-paper-a/" "Mozilla/5.0 (iPhone; …"
203.0.113.45 - - [10/Sep/2026:12:12:06 +0100] "POST /?wc-ajax=get_refreshed_fragments HTTP/2.0" 200 725 "https://www.example.com/product/example-paper-a/" "Mozilla/5.0 (iPhone; …"
203.0.113.45 - - [10/Sep/2026:12:12:08 +0100] "POST /?wc-ajax=tinvwl HTTP/2.0" 200 3228 "https://www.example.com/product/example-paper-a/" "Mozilla/5.0 (iPhone; …"
And this is 06:10 on a Tuesday on a different site. Every line is a different client, each fetching exactly one full page. No assets, no AJAX, no referer. Each one moves on:
83.99.x.x      "GET /product-category/jewellery/page/126/ HTTP/1.1" 200 56040 "-" "Mozilla/5.0 (X11; Linux x86_64) …"
57.141.20.42   "GET /product/example-ring-a/ HTTP/2.0" 200 75618 "-" "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) …"
142.252.153.95 "GET /product/example-pendant/?add-to-cart=4921 HTTP/2.0" 200 544855 "-" "Mozilla/5.0 (Macintosh; …"
85.25.185.20   "GET /product/example-necklace/ HTTP/1.1" 200 76908 "-" "Mozilla/5.0 (X11; Linux x86_64) …"
202.81.217.63  "GET /product/example-ring-b/?add-to-cart=22008 HTTP/2.0" 200 59059 "-" "Mozilla/5.0 (Macintosh; …"
85.25.185.20   "GET /product/example-bracelet/ HTTP/1.1" 200 77015 "-" "Mozilla/5.0 (X11; Linux x86_64) …"
Every one of those claims to be a desktop browser. 57.141.x is Meta’s crawler range wearing a Mac Chrome User-Agent. 142.252.x, 85.25.x and 202.81.x are hosting companies (so they’re not people using a laptop or their phone). The masked first line is Latvian home broadband: a residential proxy, somebody’s connection rented out to a scraper. That’s why its address isn’t printed here. Each line is an uncached WordPress render that nobody will ever look at.
The eyeball test tells you something is wrong. It doesn’t tell you how much. For that, we need to flex our best script-fu.
Grab the scripts
The scripts I built for this analysis are available from Github. Grab them with the following…
# Clone my ops-recipes repo
git clone https://github.com/headwalluk/ops-recipes.git

# Navigate to the scripts for this walk-through
cd ops-recipes/human-vs-bot-traffic/
The README there covers requirements (gawk, mmdb-bin, a free MaxMind licence) and which patterns to tune for your own sites before trusting the numbers.
Step 0: get the logs, and remove yourself
Everything below runs on a copy, never on the server. The scripts need gawk (minimal Debian installs ship mawk; apt install gawk).
# Five weekdays of logs, trimmed to exact dates (rotation boundaries overlap by seconds).
ssh myserver 'cat /var/www/example.com/log/access.log.{12..6}' \
  | grep -E '\[(0[7-9]|1[01])/Sep/2026:' > week.log
Before anything else, find your own monitoring. On one site a single home IP was 10,440 of the week’s page requests. An uptime checker fetching seven URLs every five minutes:
# Who fetches the same URL on a fixed schedule? Monitoring, usually yours.
gawk -F'"' '$6 ~ /HTTPie|curl|UptimeRobot|Pingdom/ { split($1, HEAD, " "); print HEAD[1], $6 }' week.log \
  | sort | uniq -c | sort -rn | head
Every script below takes OWN_IPS="…" to drop those addresses.
Step 1: what kind of request is each line?
A page, an asset, an AJAX call, an API call? One awk function, reused by every step (request-kind.awk):
# api / asset / xhr / admin / meta / page. First match wins.
# NOTE: WooCommerce REST (/wp-json/wc/v3) always counts as API. Integrations that
# poll your store are named with API_AGENTS, e.g. API_AGENTS="Omnisend|Linnworks".
if ((API_AGENTS != "" && $6 ~ API_AGENTS) || path ~ /^\/wp-json\/wc\/v[0-9]/) kind = "api"
else if (path ~ /^\/wp-(content|includes)\// || path ~ /\.(css|js|png|jpe?g|webp|svg|woff2?)$/) kind = "asset"
else if (path_and_query ~ /wc-ajax=/ || path ~ /^\/wp-json\// || path == "/wp-admin/admin-ajax.php") kind = "xhr"
...
else if (method == "GET" || method == "HEAD") kind = "page"
| Fashion accessories | Office stationery | Mobility aids | |
|---|---|---|---|
| Requests in the week | 168,373 | 123,862 | 207,179 |
| Page requests | 52.6% | 47.9% | 43.1% |
| API (integrations) | 27.6% | 0.7% | 1.0% |
| Assets | 10.9% | 29.4% | 14.9% |
| AJAX | 7.8% | 15.1% | 36.9% |
The API share on the first site is two SaaS integrations polling the store. WordPress API rate-limiting is a separate problem. From here on, we’re only looking at page requests.
Step 2: what does the User-Agent claim?
# Anything that says bot/crawl/spider, or is a scripting library, is "declared".
# Googlebot and bingbot get their own bucket because we will check them next.
gawk -F'"' -f request-kind.awk -f agent-claim.awk -e '
    request_kind() == "page" { COUNT[agent_claim()]++ }
    END { for (CLAIM in COUNT) print COUNT[CLAIM], CLAIM }' week.log
66–75% of page requests claimed to be an ordinary browser. That is the number most analytics tools start from, and it is the number that is wrong.
Step 3: is that really Googlebot?
A User-Agent is a string anyone can set. The network an IP belongs to (its ASN) is much harder to fake. MaxMind’s free GeoLite2-ASN database answers it locally: no IPs leave your machine.
# Query 142.252.156.37
$ mmdblookup --file /var/lib/GeoIP/GeoLite2-ASN.mmdb --ip 142.252.156.37

{
  "autonomous_system_number": 18779 <uint32>
  "autonomous_system_organization": "EGIHosting" <utf8_string>
}
(Debian: apt install mmdb-bin geoipupdate, then a free MaxMind licence key in /etc/GeoIP.conf.)
Count every “Googlebot”/”bingbot” page request by the network it came from:
8814  Googlebot via AS15169 Google LLC
2374  bingbot   via AS8075  Microsoft Corporation
 189  Googlebot via AS27323 Wowrack.com
   4  Googlebot via AS396982 Google LLC        <- Google CLOUD, not Googlebot
   2  Googlebot via AS8560  IONOS SE
# Real Googlebot crawls from AS15169; real bingbot from AS8075.
# CAUTION: AS396982 is also "Google LLC". It is Google Cloud, where anyone can rent
# a server. Match the ASN NUMBER, never the organisation name.
# For a stronger check on a single IP, reverse-then-forward DNS:
# host 66.249.66.1 -> crawl-66-249-66-1.googlebot.com
# host crawl-66-249-66-1.googlebot.com -> must return 66.249.66.1 againEvery site had fake Googlebots. 138 to 616 page requests in the week, from Wowrack, OVH, PureVoltage, Limestone, Amazon and a dozen hosting companies. Almost all of them (99.3%) spoke HTTP/1.1, rather than HTTP/2.0.
Step 4: classify the the “browsers”
Now the hard part: the 66–75% that claim to be browsers. Two questions per IP:
- Did anything follow the page? Any asset or AJAX request from the same IP during the week means something ran the page. Bots that fetch HTML don’t.
- What network is it on? A consumer broadband line, or a data centre?
# One line per IP: pages, follow-up requests (assets + AJAX), ASN, organisation.
OWN_IPS="203.0.113.7" ./04-browser-visitors.sh week.log > visitors.tsv

# Which networks send the most "browser" page requests, and how many of their IPs ran the page?
gawk -F'\t' '{ KEY = $4 " " $5; IPS[KEY]++; PAGES[KEY] += $2; if ($3 > 0) RAN[KEY]++ }
    END { for (KEY in PAGES) printf "%6d pages %5d IPs %5.1f%% ran it  %s\n", PAGES[KEY], IPS[KEY], 100 * RAN[KEY] / IPS[KEY], KEY }' \
    visitors.tsv | sort -rn | head -40
Across the three sites this separates cleanly:
13916 pages  1156 IPs  13.2% ran it  AS396982 Google LLC        (Google Cloud)
10895 pages   473 IPs   0.0% ran it  AS24651 Jsc Balticom       (Latvian residential ISP!)
10828 pages  2327 IPs   9.9% ran it  AS14618 Amazon.com, Inc.
 5626 pages  1743 IPs   6.8% ran it  AS16276 OVH SAS
 4000 pages   693 IPs  83.8% ran it  AS2856 British Telecommunications Limited
 2542 pages   432 IPs  71.1% ran it  AS5089 Virgin Media
 1517 pages   339 IPs  69.9% ran it  AS5607 Sky UK Limited
 1282 pages   256 IPs  75.0% ran it  AS31898 Oracle Corporation   (headless browsers)
  288 pages    63 IPs  98.4% ran it  AS25135 Vodafone Limited
UK broadband: roughly 70–98% of IPs ran the page. Clouds: mostly under 15%. But two rows break the simple rules, and they are the reason you need both signals:
- A residential ISP can be a botnet. 473 Latvian home-broadband IPs, 10,895 pages, zero follow-ups. That’s a residential proxy network: someone renting other people’s connections.
- A cloud can run JavaScript. 75% of Oracle Cloud IPs loaded assets and AJAX. Those are headless browsers, not people on Oracle’s network.
So the network wins when it says “data centre”, and behaviour decides the rest. The data-centre list is a text file of organisation-name patterns I built by reading the top 60 ASNs above (hosting-networks.txt):
# CAUTION: do NOT tag Apple, Cloudflare, Fastly or Akamai Technologies as hosting.
# They carry iCloud Private Relay and WARP traffic. Real people. A generic
# "cloud" pattern matches Cloudflare, so exempt them explicitly.
# Also avoid short patterns like "colo": it matches Colombian ISPs.
hosting
cloud
server
^Amazon
^Google LLC
^OVH
...
Step 5: classify every page request
| Class | Rule |
|---|---|
| Search engine | Googlebot/bingbot User-Agent and AS15169 / AS8075 |
| Fake search engine | Googlebot/bingbot User-Agent from anywhere else |
| Declared crawler | Honest bot User-Agent: Meta, SEO tools, AI crawlers, link previews |
| Disguised bot | Browser User-Agent from a data-centre network |
| Human | Browser User-Agent, consumer network, and the IP ran the page |
| Unknown | Browser User-Agent, consumer network, page only |
# Create classified.txt as "date hour class protocol"
OWN_IPS="203.0.113.7" ./05-classify-pages.sh week.log > classified.txt

# Parse & group classified.txt
awk '{ COUNT[$3]++; TOTAL++ } END { for (CLASS in COUNT) printf "%5.1f%%  %s\n", 100 * COUNT[CLASS] / TOTAL, CLASS }' classified.txt | sort -rn
05-classify-pages.sh uses the classic two-file awk join. NR == FNR loads the per-IP table, and FS='"' between the two file names switches the field separator as awk opens the log.
The results
Average weekday, Mon 7 – Fri 11 September 2026:
| Fashion accessories | Office stationery | Mobility aids (international) | |
|---|---|---|---|
| Page requests / day | 17,650 | 11,789 | 15,763 |
| Human | 1.6% | 15.9% | 23.9% |
| Search engines (verified) | 12.7% | 12.1% | 16.9% |
| Declared crawlers | 16.6% | 11.0% | 7.1% |
| Disguised bots (data centre) | 50.7% | 37.7% | 40.7% |
| Fake Googlebot/bingbot | 0.2% | 0.2% | 0.8% |
| Unknown (residential, page only) | 18.1% | 23.0% | 10.7% |
For every page-load driven by a human, something else fetched between 3 and 60 more. Disguised bots (browsers from data centres) were the biggest class on all three.
The fashion site is the outlier because its theme creates an endless crawl space. Every related-product “add to basket” link on every product page is a new URL. Bots love that.
The human share holds up to scrutiny. On the stationery site 63% of human page views came from UK connections. On the mobility-aids site, which sells internationally, 36% UK and 35% US. 80–85% of “human” IPs viewed one to five pages.
HTTP/1.1 is a tell, but not a verdict
| Class | Page requests over HTTP/2 |
|---|---|
| Humans | 93.8% |
| Declared crawlers | 84.0% |
| Disguised bots | 47.1% |
| Unknown | 37.8% |
| Real search engines | 23.4% |
| Fake search engines | 0.7% |
# A browser-shaped page load over HTTP/1.1 is suspicious. But real Googlebot
# mostly uses HTTP/1.1 too. So never block on protocol alone.
awk '{ COUNT[$3 " " $4]++ } END { for (KEY in COUNT) print COUNT[KEY], KEY }' classified.txt | sort -k2
When do they come?
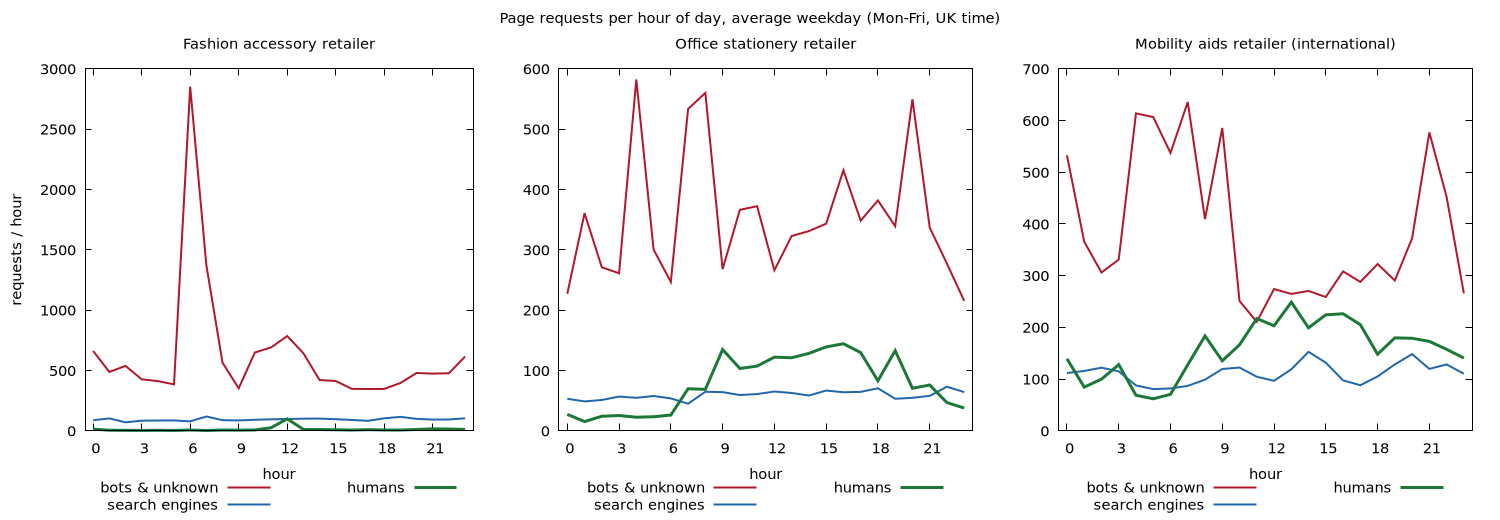
People follow the working day. On the stationery site they ramp up from 07:00, hold 100–140 an hour through the afternoon and fall away after 20:00. The international site keeps a long evening shoulder for its American customers. Search engines are a flat line: they pace themselves. Everything else arrives in bursts. The fashion site took a weekly total of 13,205 disguised-bot page requests in the 06:00 hour alone.
Caveats
- This is a classification, not ground truth. A headless browser on a residential proxy that runs JavaScript will be counted as human. A real person with JavaScript off will land in “unknown”.
- The data-centre list is hand-built from the top 60 networks. Anything smaller that isn’t listed defaults to “consumer”.
- One IP is not one person. Mobile carriers put many people behind one address, and privacy relays (iCloud Private Relay, Cloudflare WARP) look like CDNs. One Cloudflare address in the “human” bucket (164 pages, 0.9% of that site’s humans) was actually Cloudflare’s Workers egress: a script.
- A few heavy “human” IPs are almost certainly the retailers’ own staff.
So what do you do about it?
On these three shops, somewhere between one page in four and one page in sixty was rendered for a person. Everything else was machinery. Some of it you want, most of it you don’t, and very little of it will go away because you ask nicely.
What I’d take from the numbers:
robots.txtonly works on the honest ones. Declared crawlers were 7–17% of page requests. The polite ones will listen. Meta’s crawler, in my experience, does not.- Leave real search engines alone, but check they’re real. Verified Google and Bing were a steady 12–17%, paced evenly across the day. The fakes are trivial to spot by network, and there’s no reason to serve them.
- You can’t block the disguised bots one IP at a time. Thousands of addresses, often one request each, many of them on residential connections. The lever is making each request cheaper: a page cache for anonymous visitors, and removing crawl traps. URL shapes that generate endless unique, uncacheable pages. The fashion site’s add-to-cart links were exactly that, and a big part of why it sat at 1.6% human.
- Measure before and after. Every number here came from a handful of scripts and a week of logs. Run them again after a change and you’ll know whether it worked, rather than hoping.